a few more details:
Zammad version
7.1.3-8facd925.docker
Deployment uses the official zammad/zammad-docker-compose repository via Portainer. Docker-compose revision at deployment:
2e99d48
init: true is enabled for the railsserver container.
Problem
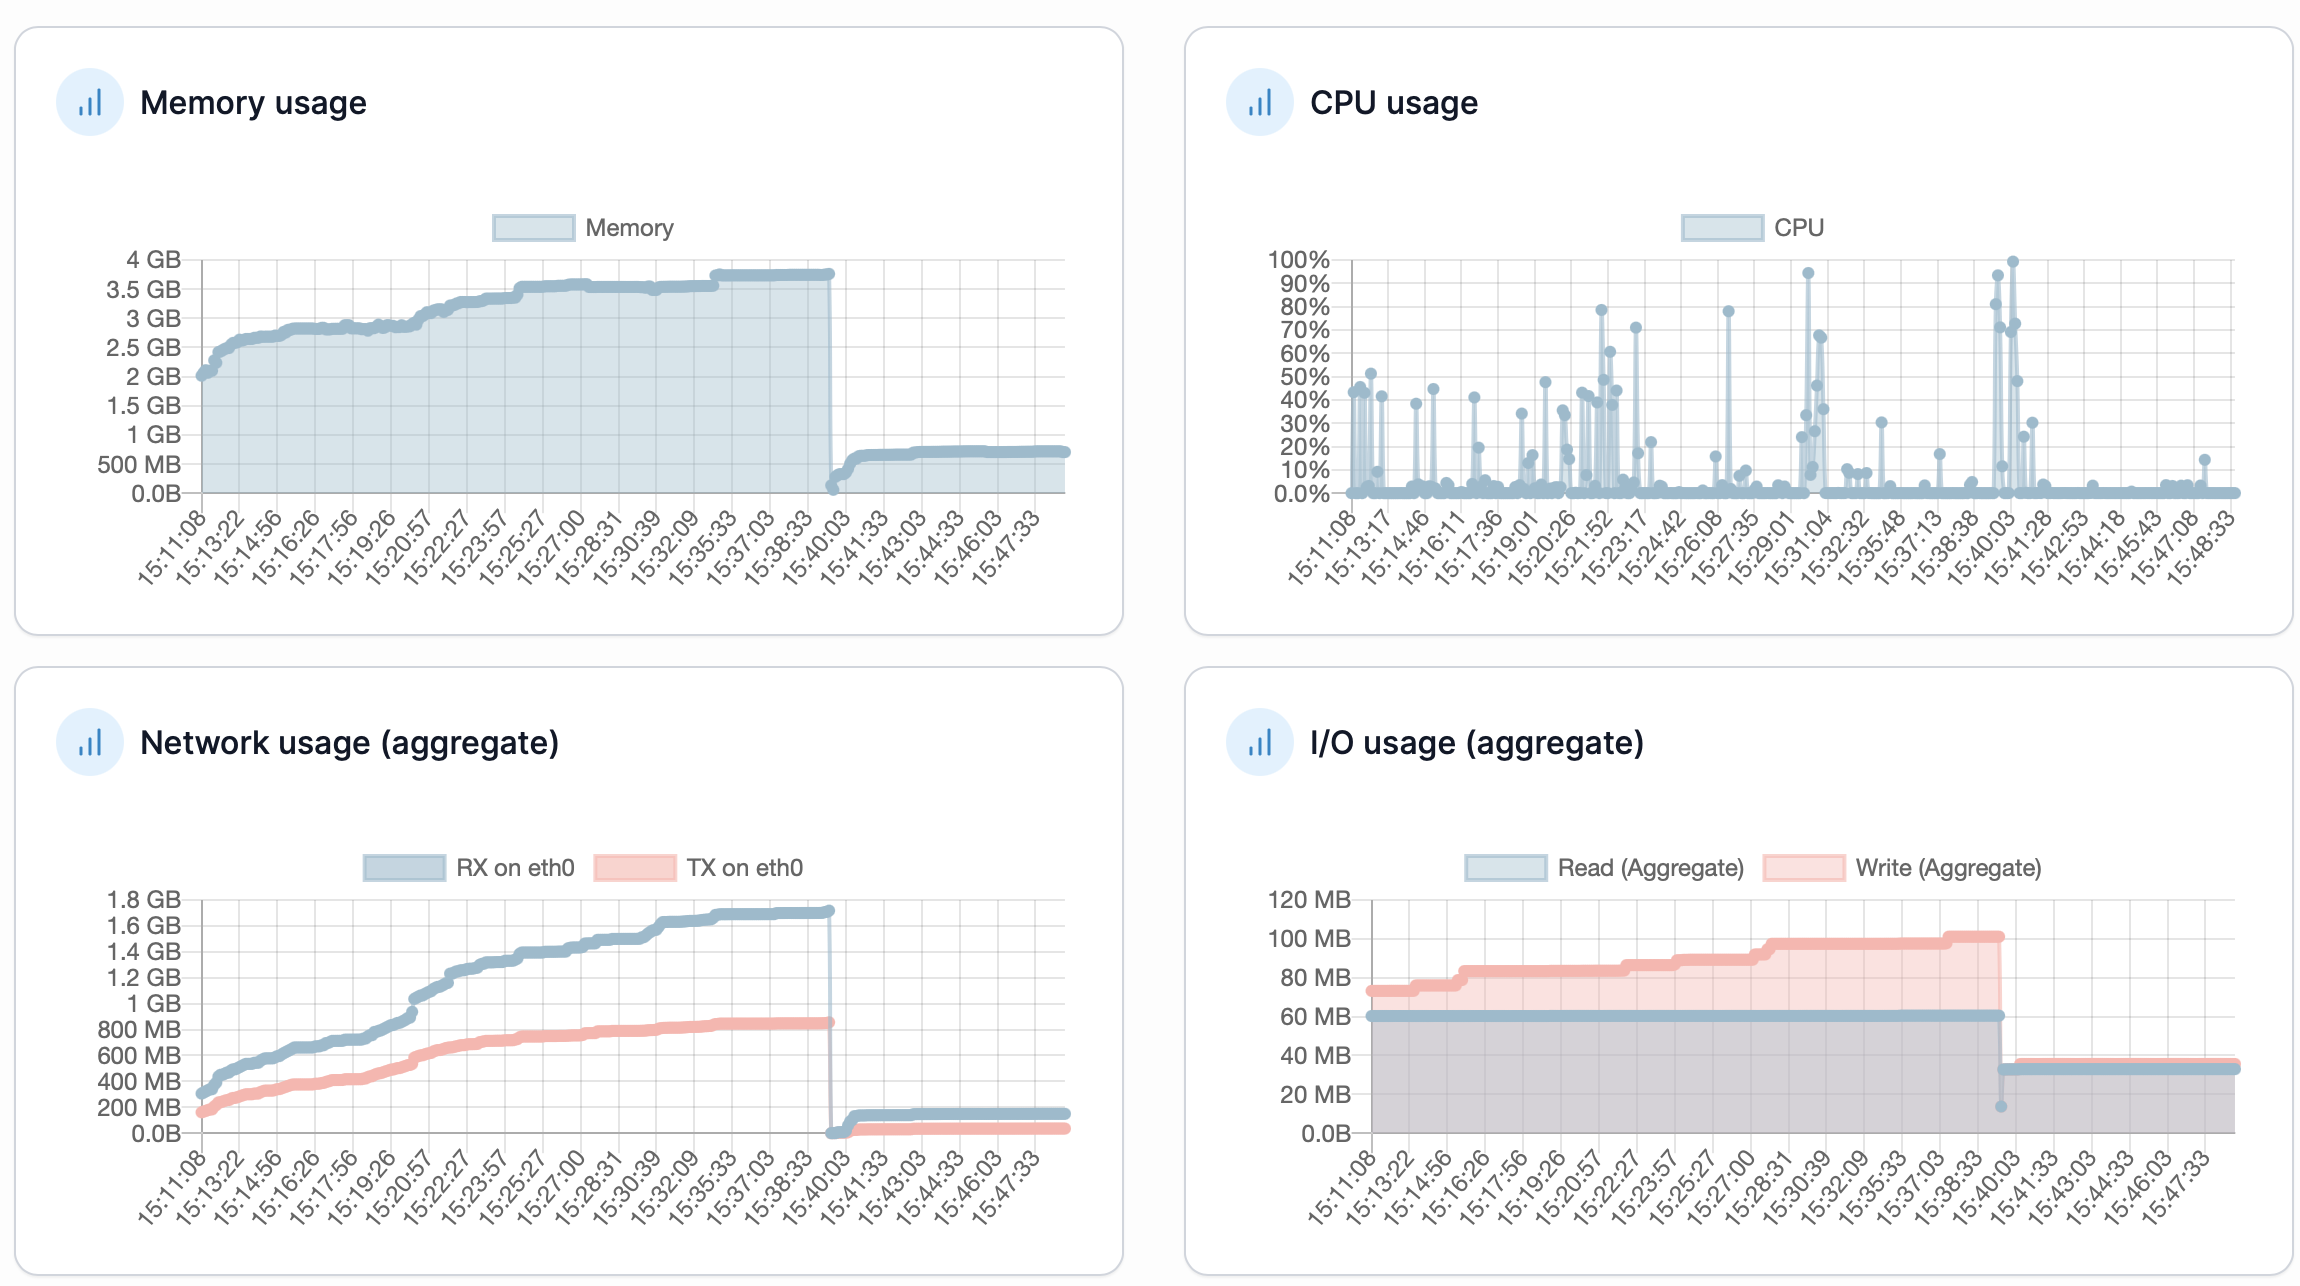
The memory usage of zammad-zammad-railsserver-1 continuously increases during normal operation and does not appear to be released. Eventually the server runs out of memory and crashes.
Restarting only the railsserver container releases the memory, after which the same growth starts again.
The memory growth is entirely attributable to the single Puma process, rather than multiple workers or zombie/child processes.
Example after approximately 54 minutes uptime:
PID    PPID   RSS      VSZ      %MEM %CPU  CMD
7      1      2524344  6598552  15.4  9.5  puma 8.0.2 (tcp://0.0.0.0:3000) [zammad]
This corresponds to approximately 2.4 GiB RSS after less than one hour.
There is only one Puma process:
PID 1: /sbin/docker-init
PID 7: puma 8.0.2
No accumulation of child/zombie processes was observed.
Memory analysis
/proc/<puma-pid>/status :
VmSize:  6598552 kB
VmRSS:   2524488 kB
RssAnon: 2487996 kB
RssFile:   36492 kB
RssShmem:      0 kB
VmData:  5184908 kB
VmSwap:        0 kB
smaps_rollup :
Rss:             2524488 kB
Pss:             2507475 kB
Shared_Clean:      27772 kB
Private_Clean:      8720 kB
Private_Dirty:   2487996 kB
Anonymous:       2487996 kB
Swap:                  0 kB
Therefore almost all of the ~2.5 GB RSS is private anonymous memory belonging to the Puma process. It is not filesystem cache or shared/file-backed memory.
Interestingly, the conventional [heap] mapping accounts for only approximately 193 MB:
[heap]
Size:       210528 kB
Rss:        192656 kB
Anonymous:  192656 kB
There are instead many large anonymous mappings. For example:
64936 kB
58760 kB
58736 kB
54004 kB
53812 kB
53712 kB
53672 kB
52736 kB
51636 kB
50716 kB
...
There were 60 anonymous mappings with sizes between 60 and 66 MB.
At the same time Puma had:
Threads: 17
(21 threads were observed during an earlier measurement.)
No allocator configuration is currently present:
env | grep -E 'MALLOC|LD_PRELOAD|JEMALLOC'
returns nothing.
This pattern may indicate substantial glibc malloc arena retention/fragmentation, although I have not established whether this is the actual cause or a consequence of application-level memory retention.
Rails GC note
A separate rails console showed:
heap_allocated_pages: 1088
heap_live_slots:      1024179
old_objects:           489505
However, these statistics are from the separate Rails console Ruby process and therefore do not represent the Puma process. I include this only to clarify that GC statistics from rails console were not used to diagnose Puma memory.
Observed behaviour
Memory starts relatively low after restarting zammad-railsserver and then grows continuously during operation. It does not return to the previous level when activity decreases.
Immediately before one restart:
Threads: 17
VmRSS:   2530956 kB
RssAnon: 2493336 kB
Eventually this growth exhausts available server memory.
Restarting zammad-zammad-railsserver-1 immediately releases the memory without requiring PostgreSQL, Elasticsearch, scheduler, etc. to be restarted.
As a temporary workaround I am monitoring the railsserver container memory and restarting only that container when it exceeds approximately 3.5 GB.
Questions
Is this memory growth known with Zammad 7.1.3 / Puma 8.0.2?
In particular:
- Is this amount/rate of Puma RSS growth expected?
- Are there known memory-retention/leak issues in Zammad 7.1.3?
- Is Zammad expected to use glibc’s default malloc arena configuration?
- Is
MALLOC_ARENA_MAX or jemalloc recommended/supported for Zammad?
- Are there Puma/Ruby diagnostics that can be enabled to identify which allocations/objects are responsible for the growth?
The important diagnostic detail is that the growth appears isolated to the single Puma process and consists almost entirely of private anonymous memory, rather than Docker cache, multiple Puma workers, or zombie processes.